
AI guardrails are layered technical and procedural controls that constrain inputs, actions, outputs, and escalation around a model or agent.
AI guardrails deserves a precise explanation because its name identifies a particular information flow, training choice, runtime mechanism, or governance boundary. Treating it as a synonym for “advanced AI” makes claims impossible to test. This guide follows the concept from its input and assumptions through its observable result, then tests the shortcut most likely to be confused with it.
AI Guardrails: Definition, Boundary, and Purpose
AI guardrails are layered technical and procedural controls that constrain inputs, actions, outputs, and escalation around a model or agent. The definition contains three practical commitments: there is an identifiable input, a transformation or decision that is characteristic of AI guardrails, and an outcome that can be evaluated against a stated objective. If one of those elements is missing, the label may describe an aspiration rather than an implemented mechanism.
Trustworthy AI requires evidence across the lifecycle. A control is meaningful only when its owner, scope, trigger, expected behavior, and verification method are explicit. For AI guardrails, this system view matters because performance can be determined by the surrounding data, interfaces, hardware, permissions, and people even when the underlying model is unchanged. A useful explanation therefore separates the model’s learned behavior from the product that decides when, where, and with what authority that behavior is used.
The nearest misleading shortcut is a single system prompt expected to enforce every boundary. It may share a visible feature with AI guardrails, yet it changes the causal story: different evidence would establish success, different resources would dominate cost, and different controls would prevent harm. The boundary is therefore operational rather than terminological.
A Five-Stage Operating Map of AI Guardrails
01Classify the request and applicable
02Constrain context, tools, and data
03Validate proposed actions before execution
04Inspect outputs and changed state
05Escalate, log, and improve from
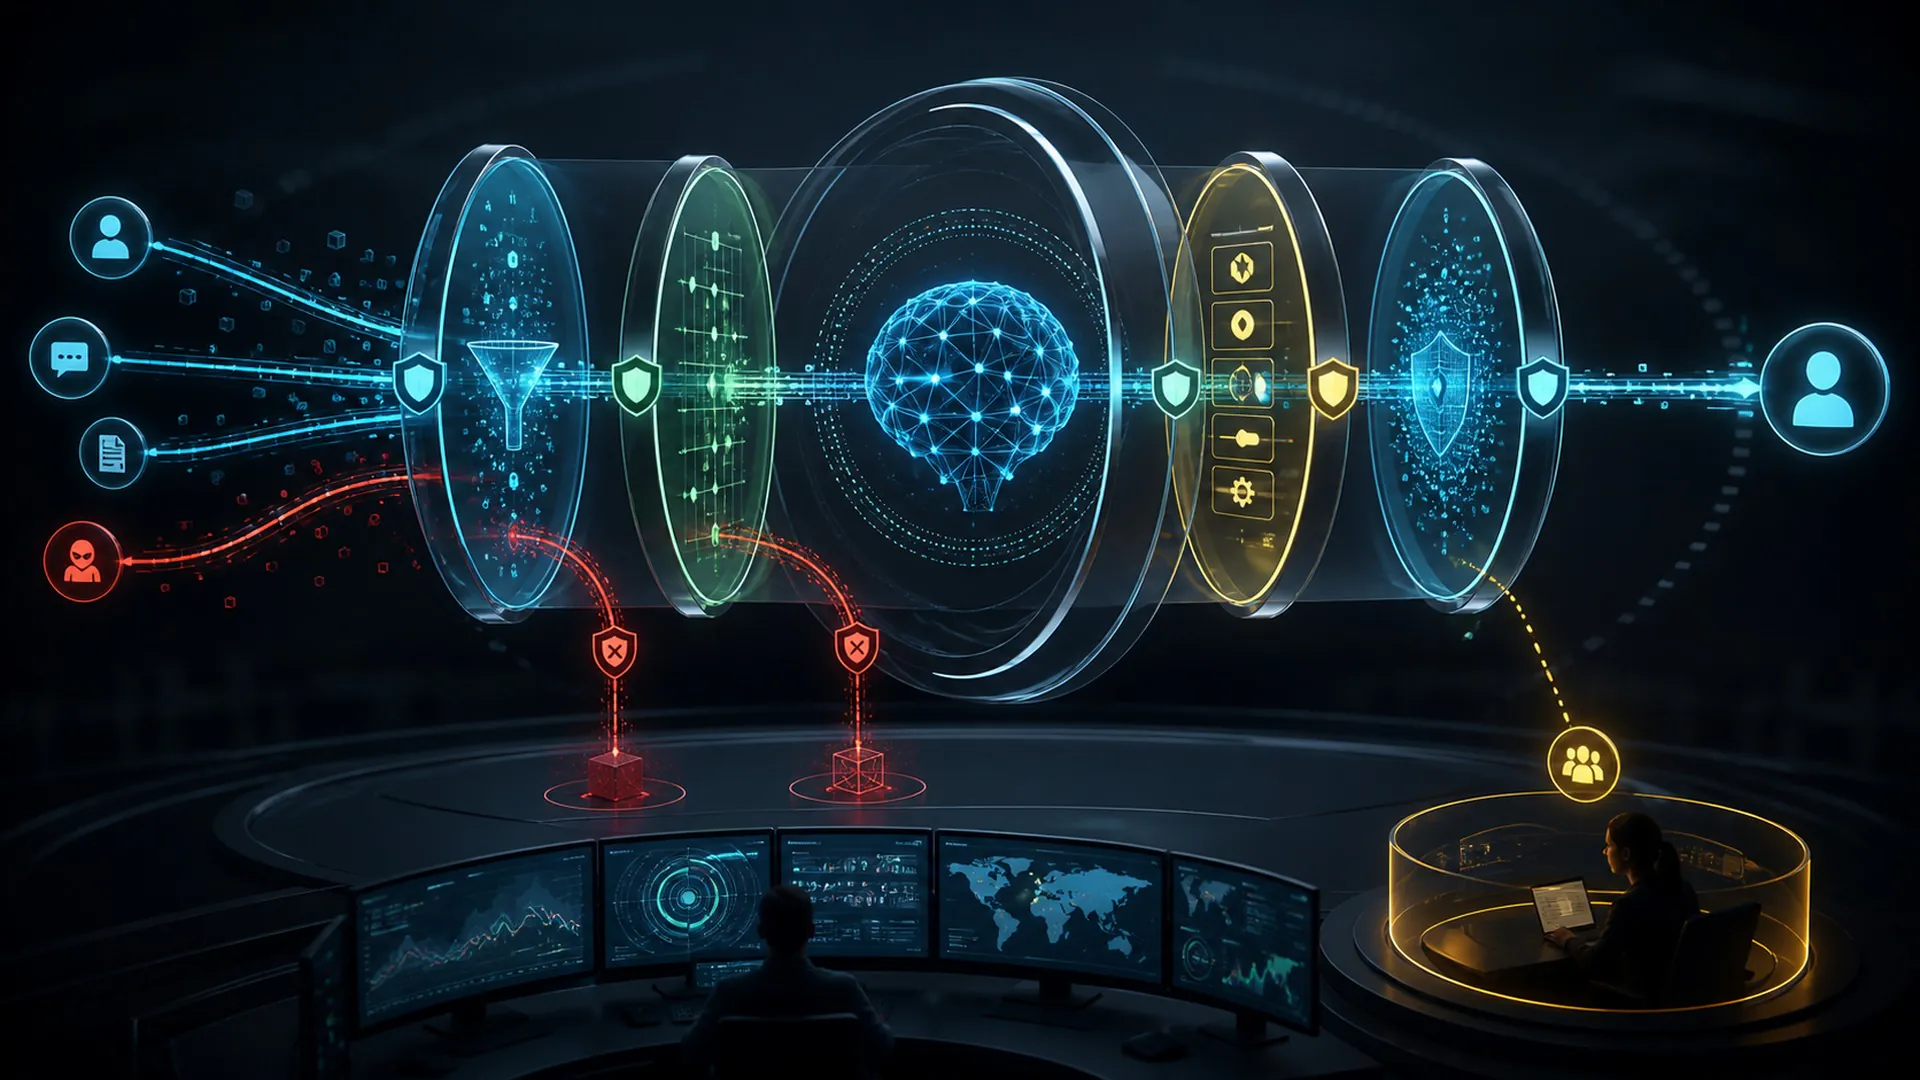
AI guardrails transforms an input into an outcome through five observable operations. The numbered explanation below follows the same order.
The diagram is a compact causal map for AI guardrails, not a claim that every implementation uses five software components. Some systems combine stages and others repeat them in a loop. The map remains useful because it forces each change in information or authority to have an owner, an input, an output, and a test.
1. Classify the Request and Applicable Policy: Input and Assumptions in AI Guardrails
At this stage of AI guardrails, the system must classify the request and applicable policy. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from a single system prompt expected to enforce every boundary and reproduce its result under the same stated conditions.
The handoff into this AI guardrails stage begins with the stated objective and should end with a result that can support constrain context, tools, and data access. Record uncertainty, rejected alternatives, resource use, and any human or software control applied at the boundary. That trace is where teams can detect whether guardrails can block legitimate work, be bypassed, or create a false sense of safety before the same weakness reaches a consequential output.
2. Constrain Context, Tools, and Data Access: Representation or Decision in AI Guardrails
At this stage of AI guardrails, the system must constrain context, tools, and data access. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from a single system prompt expected to enforce every boundary and reproduce its result under the same stated conditions.
The handoff into this AI guardrails stage begins with classify the request and applicable policy and should end with a result that can support validate proposed actions before execution. Record uncertainty, rejected alternatives, resource use, and any human or software control applied at the boundary. That trace is where teams can detect whether guardrails can block legitimate work, be bypassed, or create a false sense of safety before the same weakness reaches a consequential output.
3. Validate Proposed Actions Before Execution: Distinctive Transformation in AI Guardrails
At this stage of AI guardrails, the system must validate proposed actions before execution. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from a single system prompt expected to enforce every boundary and reproduce its result under the same stated conditions.
The handoff into this AI guardrails stage begins with constrain context, tools, and data access and should end with a result that can support inspect outputs and changed state. Record uncertainty, rejected alternatives, resource use, and any human or software control applied at the boundary. That trace is where teams can detect whether guardrails can block legitimate work, be bypassed, or create a false sense of safety before the same weakness reaches a consequential output.
4. Inspect Outputs and Changed State: Constraint and Verification Boundary in AI Guardrails
At this stage of AI guardrails, the system must inspect outputs and changed state. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from a single system prompt expected to enforce every boundary and reproduce its result under the same stated conditions.
The handoff into this AI guardrails stage begins with validate proposed actions before execution and should end with a result that can support escalate, log, and improve from incidents. Record uncertainty, rejected alternatives, resource use, and any human or software control applied at the boundary. That trace is where teams can detect whether guardrails can block legitimate work, be bypassed, or create a false sense of safety before the same weakness reaches a consequential output.
5. Escalate, Log, and Improve from Incidents: Output, Feedback, and Stop Rule in AI Guardrails
At this stage of AI guardrails, the system must escalate, log, and improve from incidents. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from a single system prompt expected to enforce every boundary and reproduce its result under the same stated conditions.
The handoff into this AI guardrails stage begins with inspect outputs and changed state and should end with a result that can support monitoring or a final decision. Record uncertainty, rejected alternatives, resource use, and any human or software control applied at the boundary. That trace is where teams can detect whether guardrails can block legitimate work, be bypassed, or create a false sense of safety before the same weakness reaches a consequential output.
Read the AI guardrails map forward to understand production and backward to diagnose failure. Forward analysis asks how one stage supplies the next. Backward analysis starts from an incorrect, slow, expensive, or unsafe result and traces which earlier assumption allowed it. The reverse path is often where a team discovers that the decisive error occurred before the model produced anything.
A Worked AI Guardrails Example
A finance assistant can draft a wire instruction but a deterministic rule and authorized reviewer must approve execution.
This example is informative because AI guardrails can be tied to observable inputs, intermediate states, and an outcome rather than judged through a polished demonstration. A rigorous test would build ordinary, difficult, and deliberately misleading cases around the scenario, preserve a baseline without the technique, and record both average performance and the severity of individual failures.
Change one assumption in the AI guardrails example and repeat the analysis. Remove a required input, introduce a conflicting signal, limit compute, alter the user population, or force the system to abstain. A mechanism that only succeeds under one carefully arranged demonstration has not established that it generalizes to the operating environment.
AI Guardrails vs. Its Most Common Shortcut
AI guardrails is often reduced to a single system prompt expected to enforce every boundary. That reduction removes the very boundary that defines the concept. It can lead buyers to compare unlike products, researchers to overstate what an experiment demonstrates, and operators to monitor the wrong signal after deployment.
Defined
AI guardrails
Core transformation
Measured outcome
Shortcut
a single system prompt expected
Skips core boundary
guardrails can block legitimate work,
The defining mechanism for AI guardrails preserves a transformation and measurable result; the shortcut removes that boundary and exposes the central failure.
Lens
Practical answer
Definition
AI guardrails are layered technical and procedural controls that constrain inputs, actions, outputs, and escalation around a model or agent.
Confusion
a single system prompt expected to enforce every boundary.
Risk
guardrails can block legitimate work, be bypassed, or create a false sense of safety.
The comparison should also identify the unit of analysis. A paper about AI guardrails may isolate a model or algorithm, while a deployed service adds retrieval, routing, caching, policy, identity, user interfaces, and monitoring. Two products can use the same headline term while implementing different parts of that stack. Ask which component performs the defining transformation and which other components are necessary for the reported outcome.
Why AI Guardrails Matters in Current AI Systems
AI guardrails matters now because AI systems are being given larger contexts, more modalities, more runtime compute, broader tool access, and deeper connections to organizational decisions. Under those conditions, what once looked like a research detail can determine latency, security, accessibility, environmental cost, product quality, or legal accountability.
The relevant measure is not whether AI guardrails can produce one impressive result. It is whether the technique improves an outcome that matters across representative conditions and does so more effectively than a simpler baseline. Report distributions, failure categories, tail latency, resource use, and affected subgroups rather than compressing every result into one average.
Monitor both technical metrics and impacts on people. Document uncertainty, preserve lineage, make escalation possible, and design recovery before the system is exposed to changing real-world conditions. Applied specifically to AI guardrails, that discipline makes the evidence portable: another team can judge whether the claimed gain is likely to survive a different model, language, hardware platform, dataset, user population, or risk tolerance.
Benefits AI Guardrails Can Deliver
The strongest reason to use AI guardrails is that it can address its intended bottleneck directly. Depending on the implementation, the benefit may appear as better grounding, a more faithful representation, improved generalization, lower latency, reduced memory movement, clearer accountability, or a safer boundary between a model proposal and a real action.
Benefits should be expressed as decisions and measurements. “More intelligent” is not an acceptance criterion for AI guardrails. A useful target might specify error rate on hard cases, recovery after conflicting evidence, cost at a percentile of traffic, human-review time, calibration, or the percentage of actions kept within a defined authority limit.
The Failure Mode That Defines AI Guardrails
The central limitation is that guardrails can block legitimate work, be bypassed, or create a false sense of safety. This failure is not an afterthought to list once development is complete. It should shape data collection, architecture, permissions, evaluation, release gates, and monitoring for AI guardrails from the beginning.
Failure to prevent: guardrails can block legitimate work, be bypassed, or create a false sense of safety.
The controls follow the same left-to-right order as the system moves toward a real-world consequence.
A control for AI guardrails is useful only if it acts before an expensive or irreversible consequence. Identify the earliest observable precursor to the failure, set a threshold or rule, assign an accountable owner, and test recovery. Depending on the use case, recovery may mean abstaining, falling back to a simpler system, requesting more evidence, escalating to a person, rolling back a model, or stopping an action entirely.
An Evaluation Plan for AI Guardrails
Begin evaluation of AI guardrails by writing the decision the evidence must support. Define the operating population, consequence of a wrong result, information actually available at decision time, and the simplest credible alternative. This prevents a benchmark from becoming the goal simply because it is easy to run.
Use an untouched test set for controlled comparisons, then validate AI guardrails in a staged operating environment. Offline evaluation makes variants comparable; shadow mode, canaries, rate limits, or approval gates reveal how real traffic, feedback loops, and people change behavior. The deployment stage should have an explicit stop condition rather than assuming every improvement deserves full rollout.
Version the inputs needed to reproduce AI guardrails: source data, preprocessing, tokenizer or encoder, model weights, configuration, prompt or policy, retrieval index, evaluation set, hardware assumptions, and serving code as applicable. Without lineage, a team cannot tell whether a changed result came from the technique, the environment, or an unnoticed pipeline edit.
Finally, ask what finding would falsify the claim that AI guardrails helps. If no result could reverse the adoption decision, the evaluation is marketing. Precommitted acceptance thresholds and a preserved confirmation set turn the exercise into evidence.
Questions to Ask Before Adopting AI Guardrails
- Objective: Which measurable bottleneck is AI guardrails intended to solve?
- Mechanism: Which of the five stages contains the distinctive transformation?
- Baseline: How does it compare with a single system prompt expected to enforce every boundary or another simpler alternative?
- Evidence: Which ordinary, difficult, adversarial, and subgroup cases were tested?
- Operations: What latency, memory, compute, energy, maintenance, and review costs appear at scale?
- Risk: How will the team detect that guardrails can block legitimate work, be bypassed, or create a false sense of safety?
- Recovery: Can the system abstain, fall back, roll back, or escalate before harm?
Primary Sources for Studying AI Guardrails
Authoritative starting points for the part of the AI stack surrounding AI guardrails include NIST AI Risk Management Framework, C2PA specifications, NIST Privacy Framework. Read them alongside the documentation for the exact model, dataset, hardware, and jurisdiction involved. A general source can define the mechanism, but only deployment-specific evidence can establish that a particular implementation is suitable.
What to Remember About AI Guardrails
AI guardrails is a defined mechanism inside a larger sociotechnical system. Its value comes from improving a specific outcome under explicit conditions, not from the label itself. The five-stage map makes its information flow visible, the comparison identifies what it is not, and the control path shows where a responsible operator can intervene.
The practical rule for AI guardrails is to define the objective, compare against a credible baseline, test the failure that matters most, and retain the evidence needed to monitor change. With those pieces in place, the concept becomes an engineering and governance choice that can be evaluated. Without them, it remains a promising name attached to an unknown operating risk.