
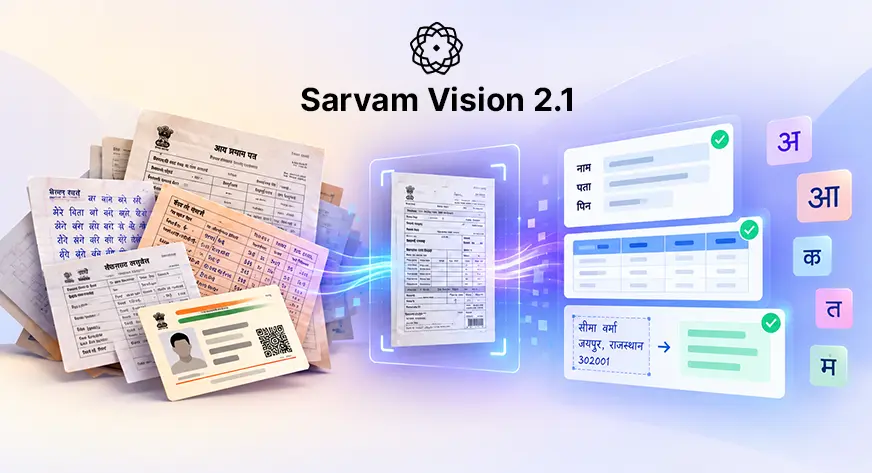
For the first time, an OCR model reads Indian languages as fluently as English documents. Sarvam Vision 2.1 breaks a long-standing trade-off. Indian businesses had to choose between structural document parsing and script recognition. Never both. Finance teams automating invoices faced this. Insurance companies processing handwritten claims in multiple states faced this. Organizations digitizing regional records faced this. All had to pick accuracy or coverage. This model does both. Let’s explore what changed, where it wins, where it struggles, and five test documents you can run yourself.
Key Features of Sarvam Vision 2.1
Pulling named fields out of a table rather than transcribing the entire grid. This works for statements, ledgers, or anything where a value only makes sense in relation to its row and column headers.
The same idea applied to form fields. The label and value sit in separate boxes. The pairing has to be inferred from layout, not reading order.
Indic Handwritten Extraction
Handwriting in Indian scripts extracted into structured fields rather than transcribed as a block. This is the hardest capability. Sarvam trained it partly on video sources to capture real handwriting variety, not just synthetic samples.
What the Numbers Actually Show
Until now, if a model was good at English document parsing it was usually mediocre at Indian languages, and the models that handled Indic scripts well were not competitive on general document structure. Those were separate tools with separate failure modes.
Each point is one system scored on both axes. Upper right is better on both at once.
Look at where the other points sit. Infinity-Parser2 Pro scores 86.1 on English, second only to Sarvam, and then collapses to 49.83 on Indic. Google Cloud Vision does the reverse: 39.6 on English document structure, but 71.76 on Indian languages, because it has had Indic OCR for years without the layout intelligence. Sarvam 2.1 is the only point in the upper right.
Where it Wins and Where it Doesn’t
The Indic Benchmark
Sarvam also released the benchmark itself: 6,909 samples, 6,609 spanning all 22 official Indian languages and 300 in English, drawn from newspapers, brochures, textbooks and historical writing dated from 1800 to the present.
The benchmark is published on Hugging Face, which matters. A vendor-built benchmark that the vendor wins is worth little on its own. A vendor-built benchmark released publicly so others can run it is a different proposition, and it is the right way to do this.
olmOCR-Bench
The community benchmark for English document parsing. It runs pass-fail checks across eight categories: arXiv maths, base text, headers and footers, tiny text, multi-column pages, degraded old scans, old-scan maths, and tables. It tests whether facts arepresent or absent rather than scoring subtle differences.
Sarvam notes that this benchmark is officially English-only but contains some contaminant samples in Chinese and other scripts. Their previous release reported on a filtered English-only set; this time they report on the official set for parity with competitors, which is the more conservative choice.
Model Math Tables OldScan MultCol Overall Sarvam Vision 2.1 90.5 91.9 55.3 82.1 87.3 Infinity-Parser2 Pro 87.4 88.9 58.0 83.3 86.1 Opus 5 90.0 89.5 54.0 85.8 85.1 Chandra-OCR2 86.5 87.5 49.2 82.4 84.5 Mistral OCR4 83.7 88.6 48.9 85.7 83.1 Gemini 3.6 Flash 86.5 85.9 48.1 78.6 82.4 GPT 6 Astra 82.6 90.9 47.0 77.8 81.8
OmniDocBench v1.6
A different measure: structural fidelity rather than fact presence. It is a composite of text edit distance, table structure scored with TEDS, formula recognition scored with CDM, and reading order, run over newspapers, textbooks, magazines and financial reports.
Model Text edit dist (lower better) Formula CDM Table TEDS Overall PaddleOCR-VL 1.6 0.0356 0.985 0.931 96.01 Sarvam Vision 2.1 0.0289 0.988 0.890 94.97 GLM-OCR 0.0374 0.984 0.895 94.71 GPT 6 Astra 0.0460 0.967 0.891 93.74 Gemini 3.6 Flash 0.0371 0.976 0.869 93.58 Opus 5 0.0471 0.967 0.856 92.51
Read that table across rather than down. Sarvam has the best text edit distance of any model at 0.0289 and the best formula score at 0.988. It loses the top spot purely on table structure, where PaddleOCR-VL scores 0.931 against Sarvam’s 0.890. Sarvam calls both benchmarks arguably saturated, which is fair when the top twelve models sit inside four points of each other.
On the Global Benchmarks
Sarvam leads olmOCR-Bench at 87.3 overall. It does not lead every category:
Category Sarvam 2.1 Best score Held by Old scans 55.3 58.0 Infinity-Parser2 Pro Multi-column 82.1 85.8 Opus 5 Tiny text 92.5 93.5 Opus 5 Tables 91.9 91.9 Sarvam 2.1 Math 90.5 90.5 Sarvam 2.1
And on OmniDocBench v1.6 Sarvam is second, not first: 94.97 against PaddleOCR-VL 1.6 at 96.01. Sarvam wins on text edit distance and formula recognition, PaddleOCR wins on table structure with a TEDS of 0.931 against 0.890.
Santhali is the clear loss. Sarvam scores 53.91 and Bodhan Indic-OCR scores 68.30, a gap of more than fourteen points. Odia is a narrower loss to Gemini 3.6 Flash, 80.01 against 81.01. Kashmiri is not a loss but it is weak in absolute terms at 54.82, the best score any model manages on that language.
Sarvam Vision 2.1 Architecture
- The vision-language model doesn’t read the page directly
- Two harnesses sit in front of it: a semantic layout parser that segments the page into regions, and a pointer network that establishes reading order
- The VLM can work at page level alone, but Sarvam found the accuracy trade-off makes harnessing worthwhile
- This is why multi-column newspapers and merged-cell tables are the hard test cases: if the harness segments wrongly, the VLM transcribes correct text in the wrong order. Fluent and wrong, which is harder to catch than garbled output
- Post-training combined supervised fine-tuning with RLVR (reinforcement learning with verifiable rewards). This fits OCR well since correctness against a known transcription is programmatically checkable.
How to Run Sarvam Vision 2.1
I could not run these myself. Sarvam’s API isn’t reachable from the environment I work in, so every result has to come from you. What I’ve done instead is build the documents, write the exact ground truth for each, and mark the specific failure to watch for. That turns a vague look at this into a scoreable test that takes about fifteen minutes.
The fastest route is the document intelligence playground, which needs no code. Upload, run, compare against the answer key.
For the API, there are two endpoints and they do different jobs:
# Digitise: full-page conversion to structured text with layout preserved
# use for documents 1, 4 and 5
POST https://api.sarvam.ai/doc-ai/job/digitise
# Extract: key-value pairs, tables, form fields
# use for documents 2 and 3
POST https://api.sarvam.ai/doc-ai/job/extract
Run document 2 through both. The difference between what digitise returns and what extract returns on the same form is the clearest demonstration of what the new extraction capability actually adds.
Conclusion
Sarvam 2.1 is the first model that doesn’t force a choice between English document structure and Indian language coverage. That’s a real result. It’s the right fit for Indian-language documents, printed or handwritten, forms and tables needing structured extraction, mixed-script pages, and production pipelines that need predictable cost.
It’s not the right fit if Santhali or Kashmiri is your primary language, if table structure fidelity is non-negotiable, or if your documents are heavily degraded historical scans, where no model performs well yet.
The model is also still 55.3 on old scans and 53.91 on Santhali. Those two numbers will decide whether it works for your documents, not the headline.
Hi , I am Sree Vamsi a passionate Data Science enthusiast currently working at Analytics Vidhya. My journey into data science began with a curiosity for uncovering insights from complex data and has evolved into building end-to-end Generative AI applications, RAG pipelines, agentic AI workflows, and multi-agent systems that solve real-world business problems.
Login to continue reading and enjoy expert-curated content.
Keep Reading for Free